Blog

Latest news and updates from DigitSpace

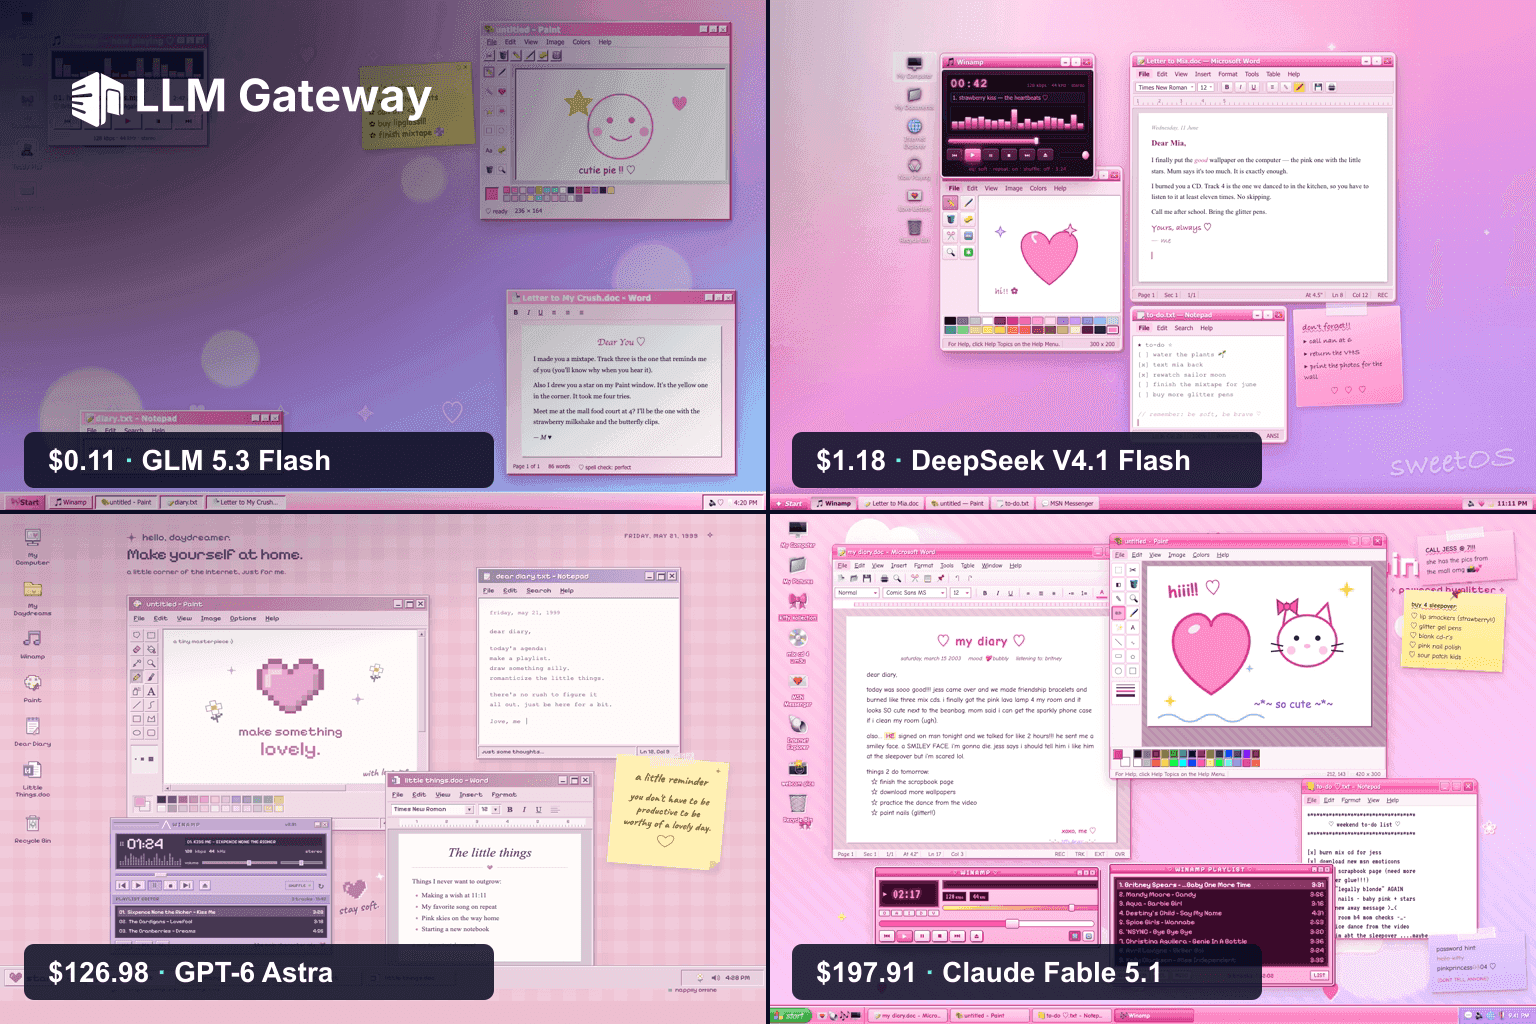
Four pink retro Windows desktops built by different AI models, in a 2x2 grid labelled with what each run cost: $0.11, $1.18, $126.98 and $197.91

Cheap vs Flagship AI Models: $0.10 vs $198

We gave six models the same coding task and measured what each one actually cost. The cheapest produced a working result for 10 cents. The most expensive spent $198 on a single index.html. This AI coding model benchmark shows where the money goes and where it stops buying quality.

September 14, 2026
A glowing boarding-gate arch on a central chip with a lit checklist beside it and light traces leading in from the edge of a circuit board, surrounded by a key, a plug, and a document icon

How to Get Your LLM API Listed on an AI Gateway

A checklist for inference providers who want their LLM API listed on an AI gateway: domain ownership, an OpenAI-compatible endpoint the gateway can actually call, honest capability flags, streaming that reports usage, flat per-million pricing, and rate limits you can sustain. Written against DigitSpace's DigitSpace Providers listing process.

September 13, 2026
A glowing dispatch radar on a central chip with light traces splitting toward three provider gates on a circuit board, surrounded by a stopwatch, a price tag, and an uptime gauge

How LLM Routing Picks a Provider: A Carrier's Guide

LLM routing on DigitSpace is an election: every provider listing a model is scored on effective price, uptime, throughput, and latency, and the lowest score wins. This guide explains the scoring from the provider's side, with the fare formula, the uptime penalty, cache-aware pricing, and the levers a carrier controls from DigitSpace Providers.

September 13, 2026
A glowing balance scale weighing coins against a memory-cache module on a circuit board, with light traces routing toward two provider chips

Cache-Aware LLM Routing Learns Your Workload

Cache-aware LLM routing learns cache-hit rates and token proportions from your project's recent model usage, so provider selection reflects the workload you actually run. Available automatically across plans, with explicit per-project overrides on Enterprise.

September 5, 2026